Alibaba’s Qwen4-Max is a new cloud AI model with a one-million-token context window and support for text, images and video. It launched on 16 November. Developers can use it through QwenCloud or Alibaba Cloud Model Studio, but Alibaba has not released the model weights for local use.
The headline numbers are 2.4 trillion total parameters and 71 billion active for each token. That second figure matters because a mixture-of-experts model does not use all its parameters on every request. Alibaba says Qwen4-Max activates 25% fewer parameters than Qwen3.8-Max at the same total size.
Qwen4-Max specs and how it compares
| Qwen4-Max | Qwen3.8-Max | |
|---|---|---|
| Total parameters | 2.4 trillion | 2.4 trillion |
| Active parameters per token | 71 billion | About 95 billion, inferred from Alibaba’s 25% comparison |
| Context window | 1 million tokens | Not compared in the announcement |
| Singapore input price | $1.50 per million tokens | $2 per million tokens |
| Singapore output price | $4.50 per million tokens | $6 per million tokens |
Model Studio lists a maximum input of 991,808 tokens, or 983,616 in thinking mode. Output is capped at 131,072 tokens, rising to 262,144 in thinking mode. The model takes text, images and video as input and produces text. It supports tool calling, web search and structured outputs, with interfaces compatible with OpenAI and Anthropic APIs. These are platform capabilities, not a claim that every existing app will work without changes.
What Alibaba’s benchmarks show
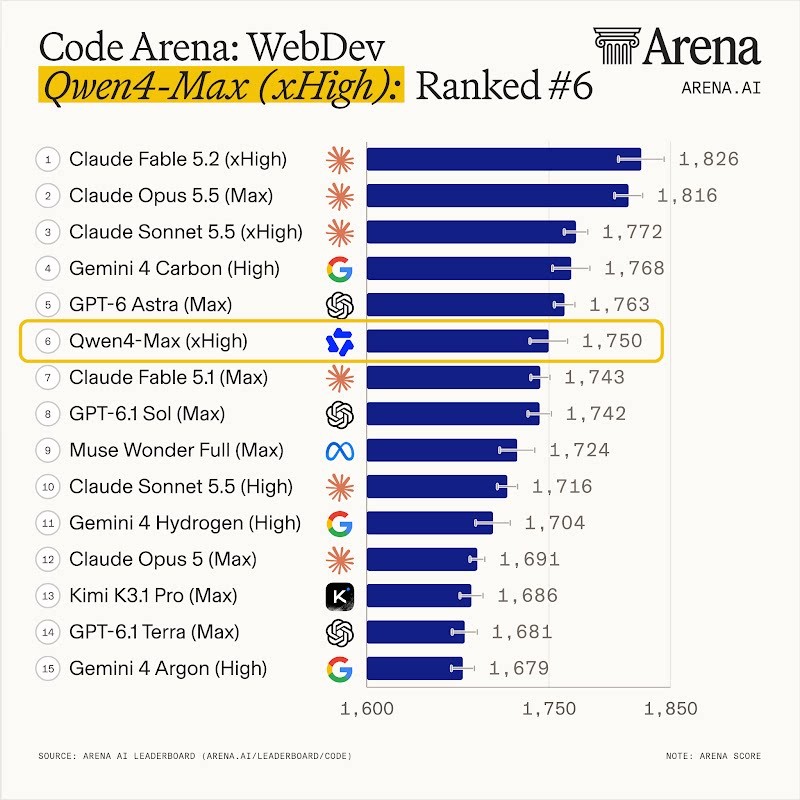
Alibaba’s release places Qwen4-Max sixth on Code Arena, a public coding leaderboard. That is a useful outside comparison, though a single leaderboard cannot tell you how the model will perform in your own codebase. The image above is the chart Alibaba used in its announcement.
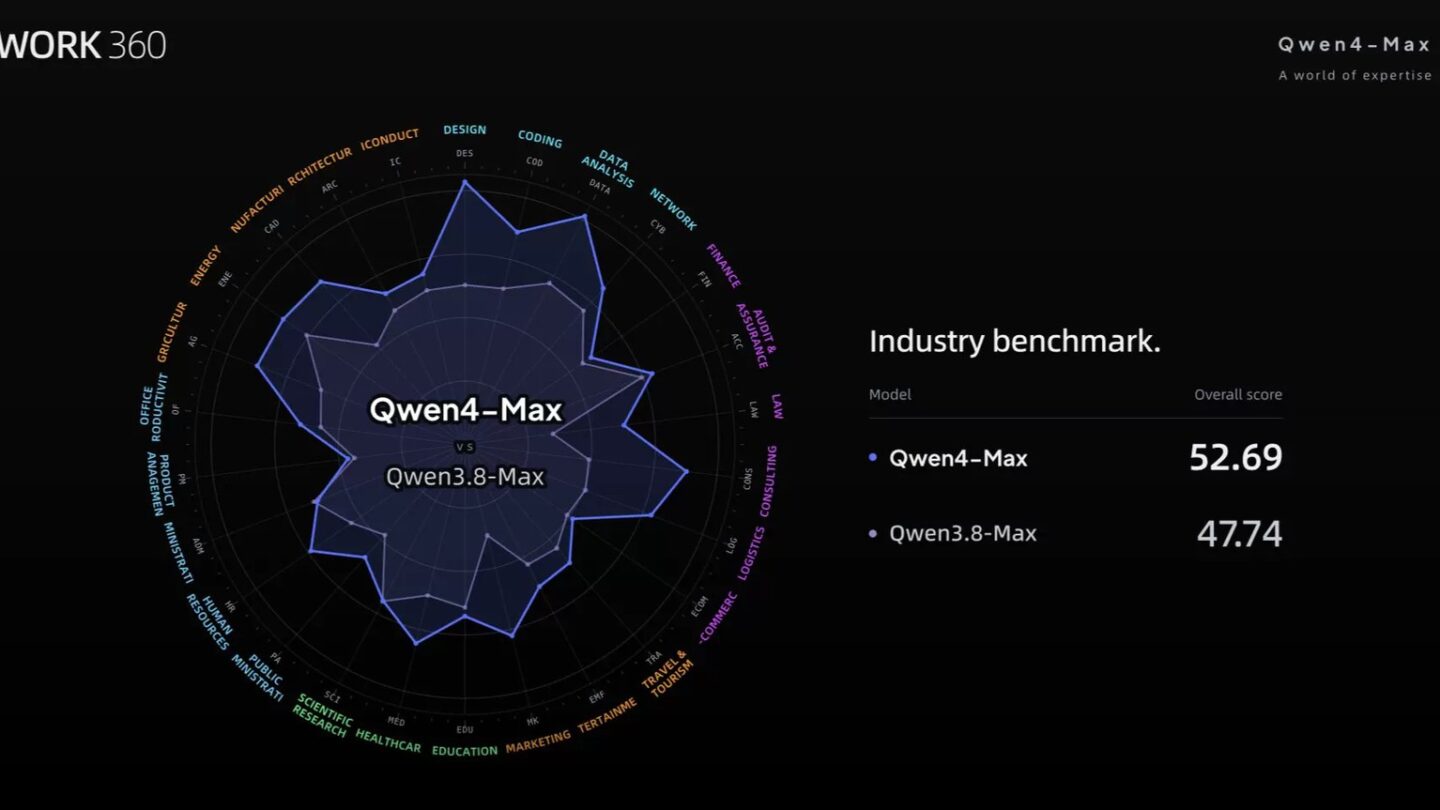
The company’s Work360 test covers tasks across 721 specialised fields. Alibaba reports that Qwen4-Max beats Qwen3.8-Max overall while using 35% fewer tokens in High effort mode and costing about 60% less per task on average. Those are Alibaba’s measurements, so I would treat them as a reason to test the model, not as proof that it is cheaper for every workload.
Qwen4-Max pricing and availability
On the Singapore deployment, which Alibaba labels International, Qwen4-Max costs $1.50 per million input tokens and $4.50 per million output tokens. Qwen3.8-Max is listed at $2 and $6 respectively on that same price list. QwenCloud also lists $0.075 per million input tokens for a cache hit. Your bill will depend on how many input and output tokens you use, whether the cache is hit, and the region you choose.
Alibaba lists lower Qwen4-Max rates in several other Model Studio regions, so Singapore’s prices are not a universal rate for everyone outside China. The Singapore listing includes a one-million-token free quota, valid for 90 days under Alibaba’s activation rules. Check the region and current pricing before building a cost estimate.
Developers in India can access the hosted model through QwenCloud or Model Studio with an account. Alibaba also says it is available in QwenWork and QwenStudio. That makes it different from downloading an open-weight model to run with Ollama, and from using a free chatbot plan in a browser. Alibaba says smaller open-weight Qwen4 models are coming, but it has not given a release date in this announcement.
Should you try it?
Qwen4-Max is worth testing if you already use Qwen APIs, need long prompts or want to compare a lower-priced flagship with your current model. Run the same real tasks through both models and compare quality, latency and the final bill. Alibaba’s demonstrations in manufacturing, cloud scheduling and scientific research are interesting, but they are company showcases rather than independent evidence for your workload.
The main limitation is straightforward: Qwen4-Max is hosted. You cannot download its weights or keep inference entirely on your own machine. Model Studio’s capability table also marks batch inference and fine-tuning as unsupported for this model. If either is essential, check another model before moving work over.